

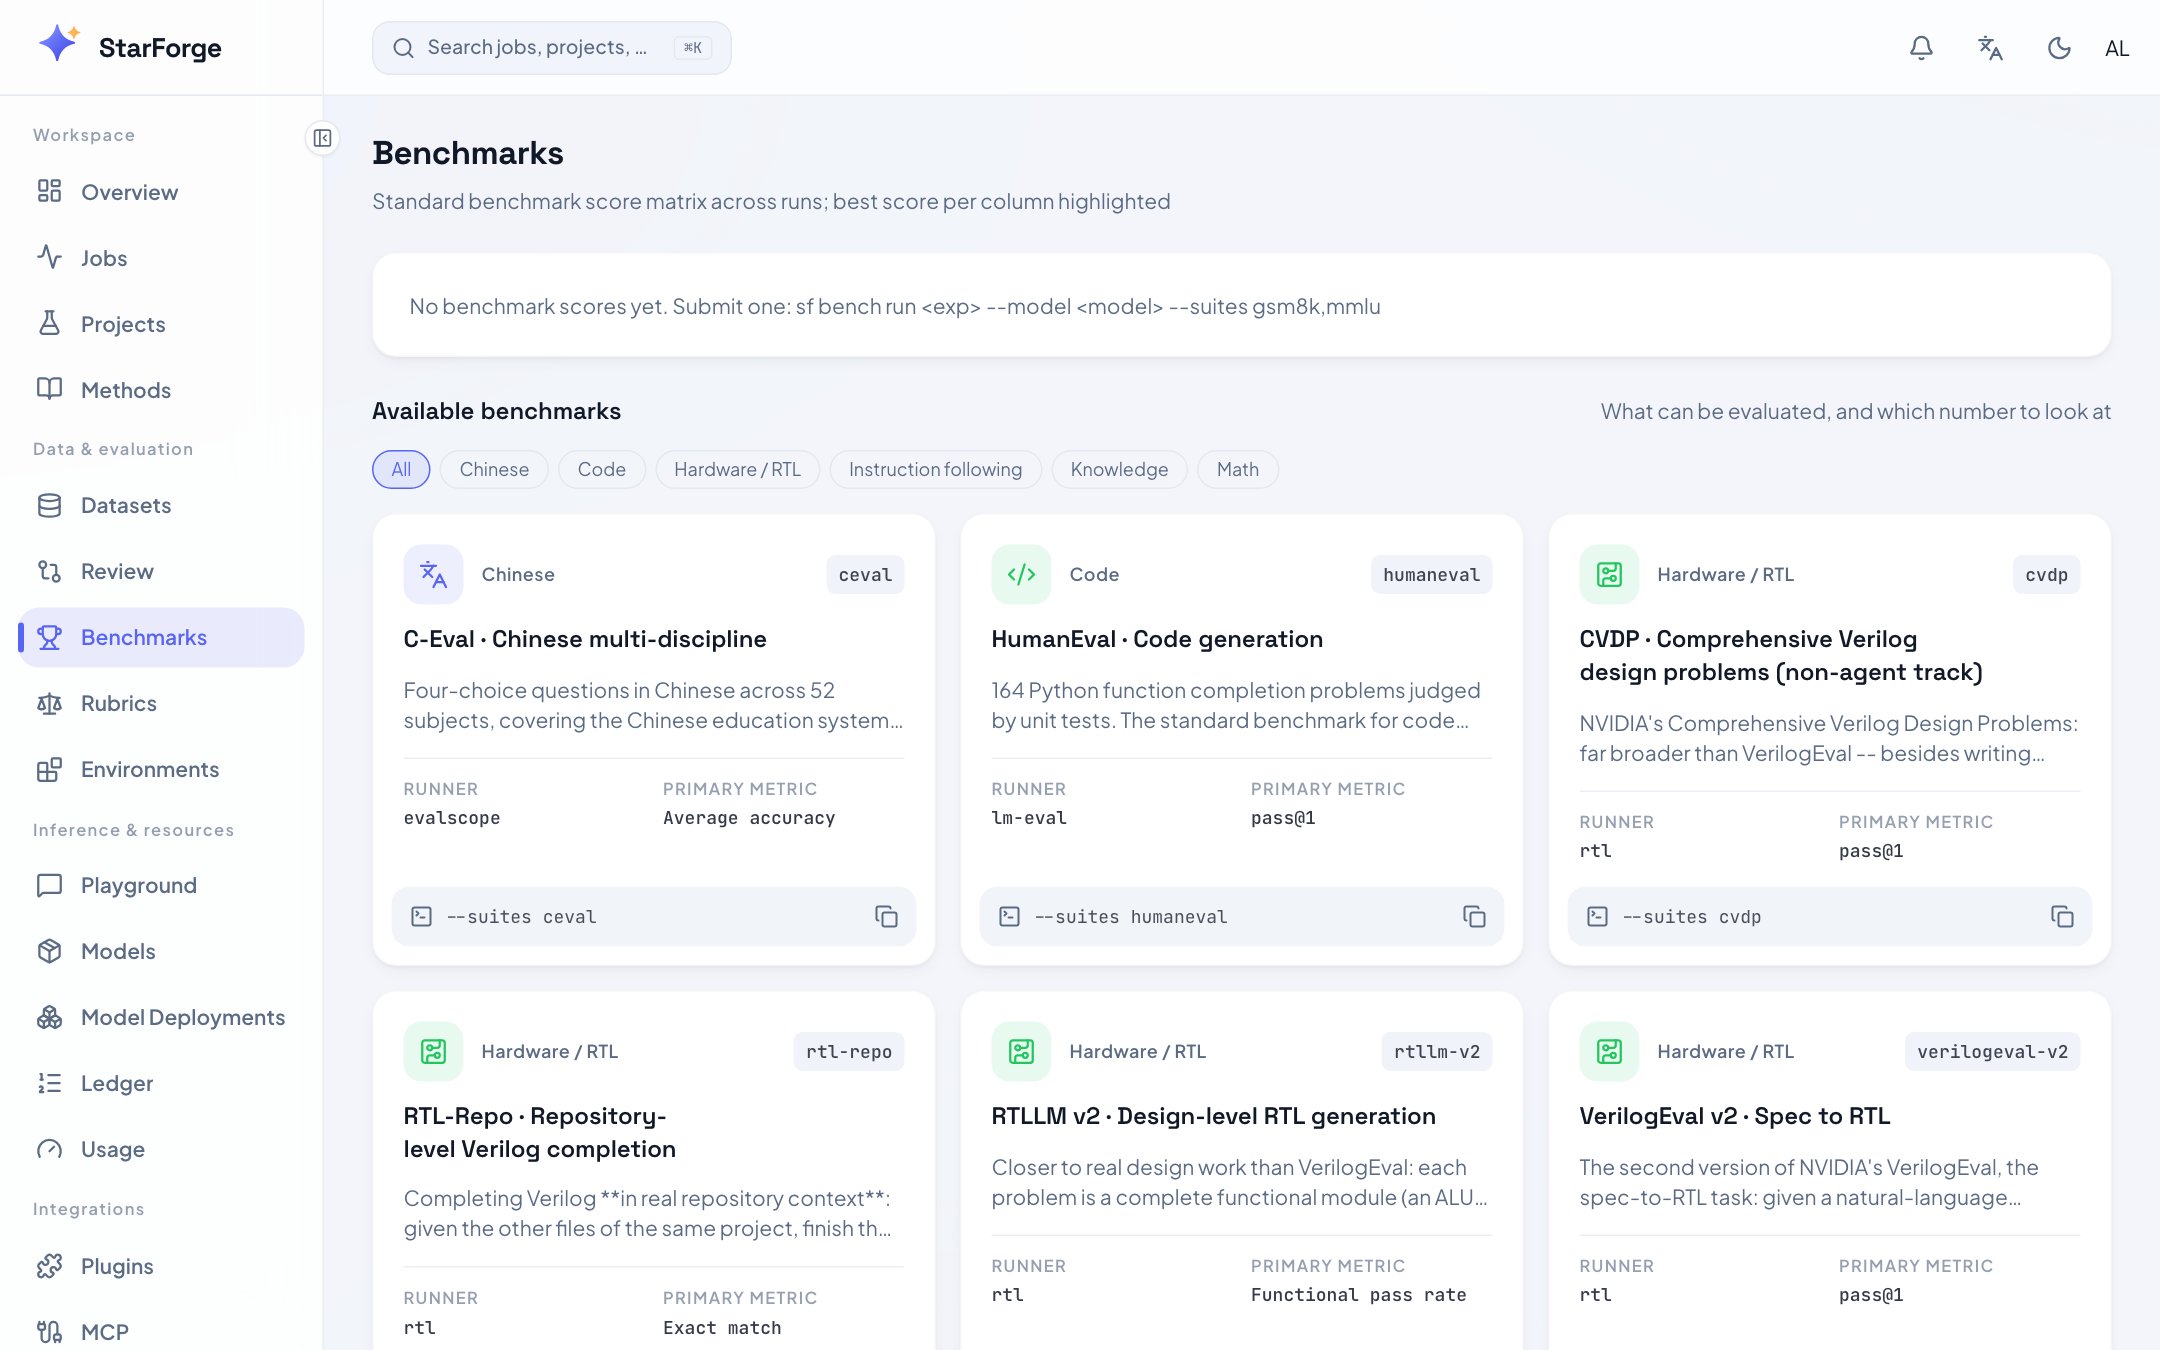
Benchmarks board. Empty until you run tp bench.
tp bench has produced, on one matrix at /benchmarks. Comparable across runs,
methods and base models.
What you see
The sample count matters. A score measured with
--limit 20 is not comparable with a full one,
and the cell is where you see that.
What you can do
Benchmark the base model before you train. Without that row the board has no reference frame and
every improvement is a number with nothing to compare against.
Where the numbers come from
tp bench submits an evaluation job that runs lm-eval, evalscope or the RTL harness inside the
platform’s evaluation image. Scores are ingested idempotently: re-reporting the same run and
benchmark updates the row rather than adding a second one.
Every runner obeys the same score contract, so the same benchmark is comparable whichever one ran
it. Each metric also carries a declared direction, so the board knows which way is better without
guessing.
Externally produced scores enter the same matrix, labelled as such. See
reporting from an external harness.